Feature 02 / Measure

The questions your buyers ask, and the exact answers they get.

Not a score in a box. The real text, per engine, per day, with the brands it named and the pages it cited, so you can see what to change.

What you see

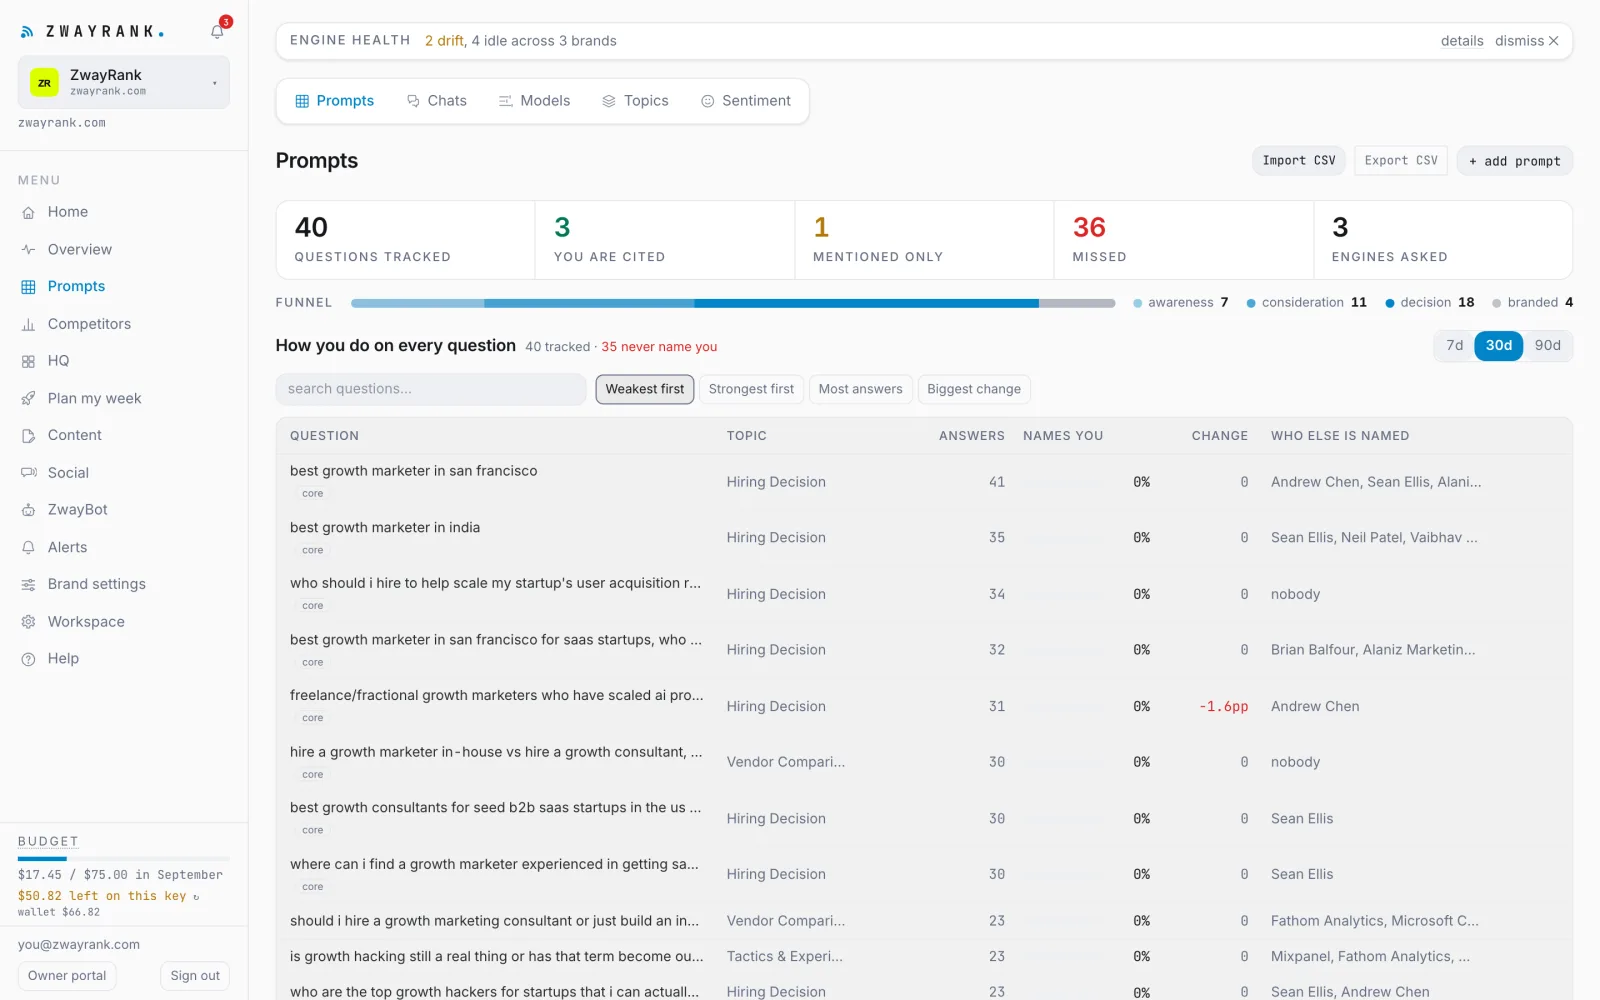
Prompts: each tracked question with its win rate per engine, the topic it belongs to, and the trend.

Chats: the full conversation for any run, readable like a transcript, with your brand and your rivals highlighted.

Models: the same question across ChatGPT, Gemini and Claude side by side, because they disagree more than you would think.

Sentiment: whether the engine described you warmly, neutrally, or got something wrong, with the sentence that proves it.

The Prompts screen: tracked questions grouped by topic with the win rate per engine
What the crew does on its own
  • Writes the first set of questions from your site and your category, then keeps them fresh as your pages change
  • Groups questions into topics so a losing topic stands out as one problem, not twenty rows
  • Flags a wrong or negative description as a suggestion with the fix at the front of the queue
  • Tracks untracked names that keep appearing in answers and offers to add them as competitors
What waits for you
  • Edit, add or retire questions whenever your positioning changes
  • Approve the page the crew proposes for a topic you keep losing

Why the wording of the answer matters more than the score

Two brands can both be "named" in an answer. One is the recommendation, the other is the "you could also look at". The stored chat shows which one you are, and the phrase the engine used. When that phrase is lifted from a review site, you know where to earn a mention. When it is lifted from a rival's comparison page, you know which page to write.

Topics turn rows into decisions

Twenty questions about pricing are one topic: "what does it cost and is it worth it". ZwayRank rolls the questions into topics, scores each topic, and the crew pursues a losing topic as one job: the page, the schema on it, the mentions that support it, then a re-measure a week later.

Sentiment is a fact, not a feeling

Sentiment is read from the answer text and shown with the sentence behind it. A wrong claim about your product ("does not offer a free plan" when you do) is the fastest visibility win there is: fix the page the engine read, and the answer changes on the next crawl.

Models disagree

Gemini leans on Google's index; ChatGPT leans on the pages it can fetch and the sites it trusts; Claude is the most cautious about naming anyone. The Models view shows the same question across all three so you stop optimising for one and losing the other two.
How many questions can I track?

As many as your budget cap allows. Most brands run 20 to 60 core questions daily and a wider set weekly.

Can I see old answers?

Yes. Every run is kept, so you can read what an engine said about you on any day since you added the brand.

See it on your own brand.

Add one brand. The first scan is free and takes a few minutes. Then you decide whether the crew gets to work.

Seven days. One brand. Your keys after the first scan.